 NexGPU-算力租赁,GPU服务器,GPU云算力,AI服务器租用-新闻博客

Is Running Inference on an A100 80GB a Waste? Decide by Model Size, Concurrency, and Context
Determine whether an A100 80GB is overkill or necessary for your LLM inference workload based on model size, concurrency, and context length.

Can Two L40S Replace One A100? A Four-Category Decision by Task Bottleneck
Two L40S GPUs offer 96GB VRAM and FP8 advantages but lack NVLink and high memory bandwidth, so whether they can replace an A100 depends on whether your workload is bottlenecked by compute/memory capacity or by inter-GPU communication and memory bandwidth.
Is the L40S Enough for Stable Diffusion? A Breakdown by SD 1.5, SDXL, Flux, and LoRA Training
The L40S is more than enough for most Stable Diffusion image generation tasks, with 48GB of VRAM providing headroom, but its value depends on whether your workflow can utilize that extra memory.
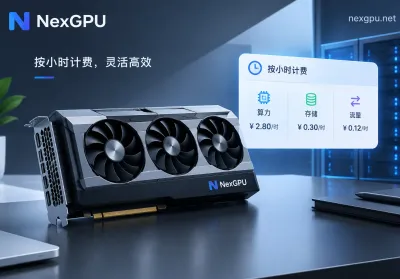
How Much Does an L40S Cost Per Hour? Check the Real-Time Rate First, Then Calculate the Full Task Cost by Compute, Storage, and Traffic
Learn how L40S hourly pricing works on NexGPU and how to estimate the total cost of a task by breaking it down into compute, storage, and traffic.
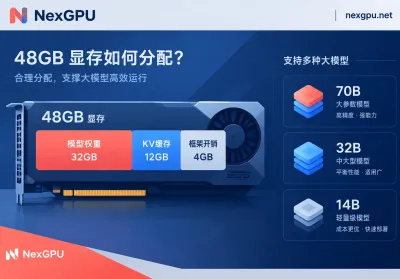
How Large a Model Can 48GB of VRAM Run? Accuracy and Context Limits for Inference and Fine-Tuning
A practical guide to the largest models you can run for inference and fine-tuning on a single 48GB GPU, including precision, context length, and concurrency trade-offs.
