 NexGPU-算力租赁,GPU服务器,GPU云算力,AI服务器租用-新闻博客
When GPU utilization won't go up during multi-GPU inference, in most cases the GPUs are not broken. The problem usually comes from one of the following five things:
- You are looking at the wrong metric
- Too few requests, the GPUs are not fed enough
- Inter-GPU communication is slowing down computation
- The parallelism strategy does not match the model and hardware
- The CPU cannot feed data to the GPUs fast enough
It is recommended to troubleshoot in this order. The first two steps require almost no configuration changes, yet they can rule out more than half of all misjudgments.
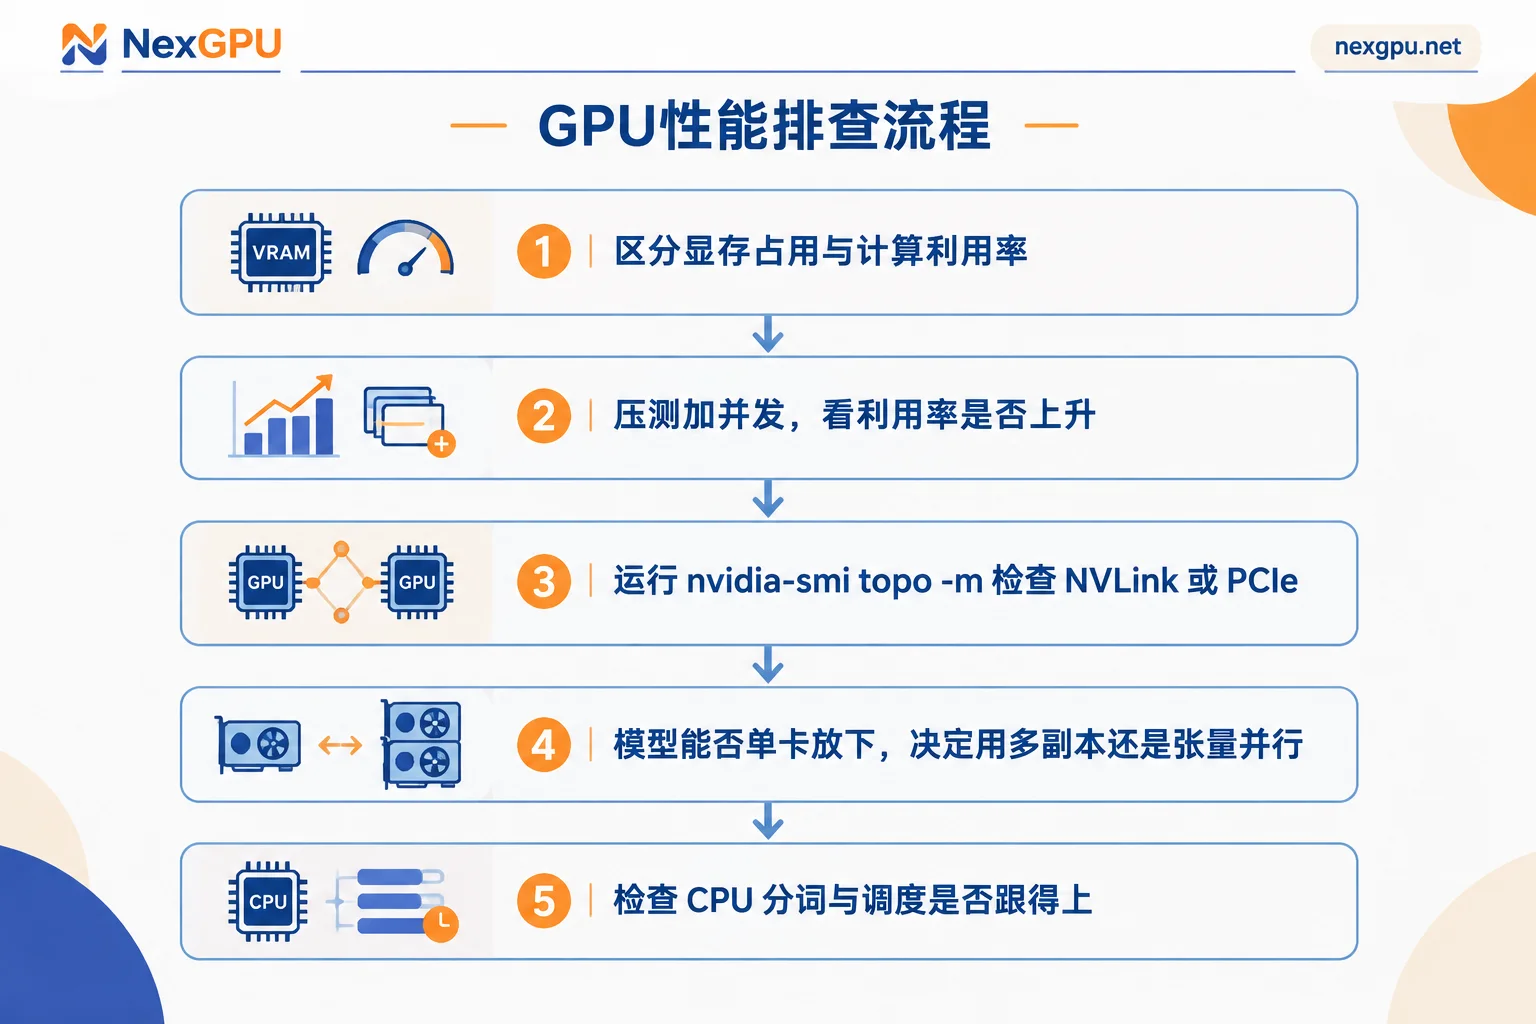
Step 1: Confirm which kind of “utilization” you are looking at
VRAM being full does not mean compute is running. Take vLLM as an example: --gpu-memory-utilization defaults to 0.9. As soon as the service starts, it reserves about 90% of VRAM in advance for model weights and the KV Cache pool, so nvidia-smi will immediately show VRAM as nearly full. This only means VRAM has been allocated ahead of time; the compute units have not started working. When no requests are coming in, compute utilization is 0.
nvidia-smi's GPU-Util is also just a rough metric. It reflects how much time during the sampling period the GPU spent executing tasks, but it cannot show how busy the compute units actually are. To determine whether the GPU is stuck on compute, VRAM reads/writes, or communication, it is better to use DCGM or Nsight Systems to inspect SM activity, memory bandwidth usage, and communication time.
Step 2: Add enough load first, then draw conclusions
Large model inference has two phases:
- Prefill: processes the entire input at once, with a large amount of computation, so GPU cores easily run full.
- Decode: generates output tokens one by one. For every token generated, the model weights must be read from VRAM once, but only a small amount of computation is performed each time.
Therefore, the bottleneck in the Decode phase is mainly memory bandwidth, not compute. When concurrency is low, the compute units spend most of their time waiting for data to be transferred from VRAM, so low compute utilization is normal. At this point, if you check memory bandwidth, it is often already close to the limit.
Improving utilization depends on increasing batch size: the more requests processed simultaneously, the more computation can be completed per weight read. The way to judge is straightforward:
- Run a stress test and observe changes. Use input and output lengths close to real business workloads for stress testing, gradually increase concurrency, and observe whether throughput and utilization rise together. If they rise together, it means the earlier low utilization was simply due to insufficient load, and the configuration itself is fine.
- Online traffic is inherently low. Then multiple GPUs will naturally sit idle. Tuning parameters will not help much; you should consider reducing the number of GPUs instead.
- Check
--max-num-seqs. This parameter limits the number of sequences processed simultaneously. If set too small, it suppresses batch size. Increasing it appropriately can fill the GPU, but the upper limit is constrained by the VRAM available for KV Cache. The longer the context, the fewer sequences can be processed simultaneously. For how to estimate VRAM, see What to Do When Long-Context Inference Runs Out of VRAM. - If utilization fluctuates sharply, try Chunked Prefill. It splits long inputs into small chunks and schedules them together with requests being generated, avoiding a long prompt monopolizing time while other requests wait. vLLM controls this with
--enable-chunked-prefill, and some versions have it enabled by default; refer to the documentation for your version.
Step 3: Check inter-GPU topology to see whether communication is dragging you down
If utilization still won't go up after increasing concurrency, and you are using tensor parallelism (TP), the next step is to check the inter-GPU connections.
TP splits the computation of each layer across multiple GPUs. Every Transformer layer requires multiple All-Reduce operations, meaning the GPUs synchronize their computation results. If the GPUs have NVLink between them, synchronization is fast. If they only use PCIe, or must go through the CPU across NUMA nodes, communication latency rises multiples-fold. After the GPU finishes a segment, it must stop and wait for synchronization to complete, so utilization naturally drops.
First run:
nvidia-smi topo -mIn the output matrix, the meanings of the markers at the intersection of two GPUs are as follows:
NV#: NVLink exists between the two GPUs, suitable for TP.PIX/PXB: Through a PCIe switch chip; usable, but communication is noticeably slower than NVLink.PHB: Through the CPU's PCIe host bridge.SYS: Across CPU sockets (NUMA nodes), the slowest communication.
If the GPUs used for TP are connected via PHB or SYS, and the TP scale is not small, then the low utilization is very likely mainly caused by communication waiting. In this case, you can use the Nsight Systems timeline to confirm further by checking what proportion of each step is taken by NCCL communication.
Step 4: If the model fits on a single GPU, do not split tensor parallelism
Many utilization problems are actually caused by choosing the wrong parallelism strategy.
- Small and medium models (such as 7B–14B), or models that fit on a single GPU after quantization (AWQ, GPTQ, FP8, etc.): Forcing them onto multiple GPUs with TP only adds communication and synchronization overhead. If you are pursuing total throughput, a better approach is usually multi-replica data parallelism: each GPU independently runs a complete instance (use
CUDA_VISIBLE_DEVICESto bind instances to different GPUs), with the frontend doing load balancing. There is no synchronization between GPUs, making it easier for each to run at full capacity. - Models too large and must be split: try to ensure TP only runs between GPUs interconnected by NVLink. On machines without NVLink, using very large TP usually does not work well.
- Pipeline parallelism (PP): requires enough requests to fill the pipeline. When concurrency is insufficient, a large amount of idle waiting occurs between stages (pipeline bubbles), and utilization similarly won't go up.
For details on choosing between TP and PP, see How to Choose Between Tensor Parallelism and Pipeline Parallelism; if you are concerned about why throughput does not double after adding GPUs, see Why Multi-GPU Inference Throughput Does Not Double. If you are running an MoE model, you also need to additionally consider communication caused by expert routing and imbalanced expert load; see How to Troubleshoot Imbalanced Expert Load in MoE Models.
Step 5: Check whether the CPU is failing to feed data
If utilization alternately rises and falls, periodically dropping to the bottom, while a CPU core remains fully occupied for a long time, you should suspect the CPU side has become the bottleneck.
Common causes include: too few CPU cores or low clock speed; input tokenization and output detokenization not being sufficiently asynchronous under high concurrency; and the Python global interpreter lock (GIL) limiting scheduling threads. The result is that the inference engine cannot replenish new tasks for the GPU in time, and the GPU can only spin idle.
Approaches to handle it:
- Reserve enough CPU cores for the inference process, and do not run it together with other heavy-load services.
- Upgrade the framework version. Improvements in asynchronous tokenization and scheduling vary by version; refer to the official documentation.
- Move text preprocessing that can be done in advance to the service frontend as much as possible.
Symptom reference
| Symptom | More likely cause | What to do first |
|---|---|---|
| VRAM nearly full, compute utilization 0 | VRAM pre-allocation, no requests | Connect requests or run a stress test before checking again |
| Low utilization at low concurrency, rises after adding concurrency | Decode limited by memory bandwidth, insufficient load | Increase max-num-seqs, or reduce GPUs |
| Still won't go up after adding concurrency, using TP | Inter-GPU communication bottleneck | Run nvidia-smi topo -m to see whether PCIe or cross-NUMA is used |
| Small model on multi-GPU TP, per-GPU utilization all low | Unsuitable parallelism strategy | Switch to single-GPU multi-replica |
| Utilization periodically drops off a cliff, one CPU core fully loaded | CPU cannot feed data | Add CPU resources, check tokenization and scheduling |
Low utilization directly affects your bill
For hourly-billed machines, GPU idle time is billed as well. After troubleshooting, if you confirm that business traffic itself is insufficient, then rather than tuning parameters, the more cost-effective approach is to reduce the number of GPUs or switch to single-GPU plus quantization.
On NexGPU, compute is billed by the hour and metered by the second. After shutdown, compute is no longer billed, but storage fees continue to be charged; only after the instance is destroyed do all fees stop. If the multi-GPU machines started during the testing phase are confirmed to be unnecessary, remember to destroy them after saving your data.
If troubleshooting confirms that large-scale TP is indeed needed, choose a model with NVLink between GPUs. You can first check rentable nodes on the pricing page; after renting the machine, the first thing to do is run nvidia-smi topo -m to confirm the interconnect method before deploying the model. If you need to use multiple GPUs long-term or evaluate cluster solutions, you can directly contact us to discuss the configuration.



